See how the code was written, not just whether it passed
Your engineers get a ranked shortlist instead of a pile of zips: hidden-test results, a Claude review and the trail of how each submission was written — evidence they can read and overrule, never a suspicion score.
Hidden tests
Every submission runs against your own tests the candidate never sees, so pass rates hold up when someone asks why.
A Claude review
Strengths, risks and the questions worth asking in the interview, tied to the lines that prompted them.
The process trail
Editor telemetry, every visible-test run, the full AI conversation when you allow it, optional commit history, peer similarity and public-code matches.
What your team actually looks at
Real screens from the product: the report a reviewer decides from, the integrity evidence behind it, what the candidate sees, the PDF your hiring manager gets, the ranked results, analytics, the task library and the free CV screener.
Review
One submission, all of the evidence
Key Features
Score with its execution and review weights
Hidden-test result for every case
Paste, focus and typing telemetry from the editor
Every visible-test run before submit
devparser.it/dashboard/assessments/42/review
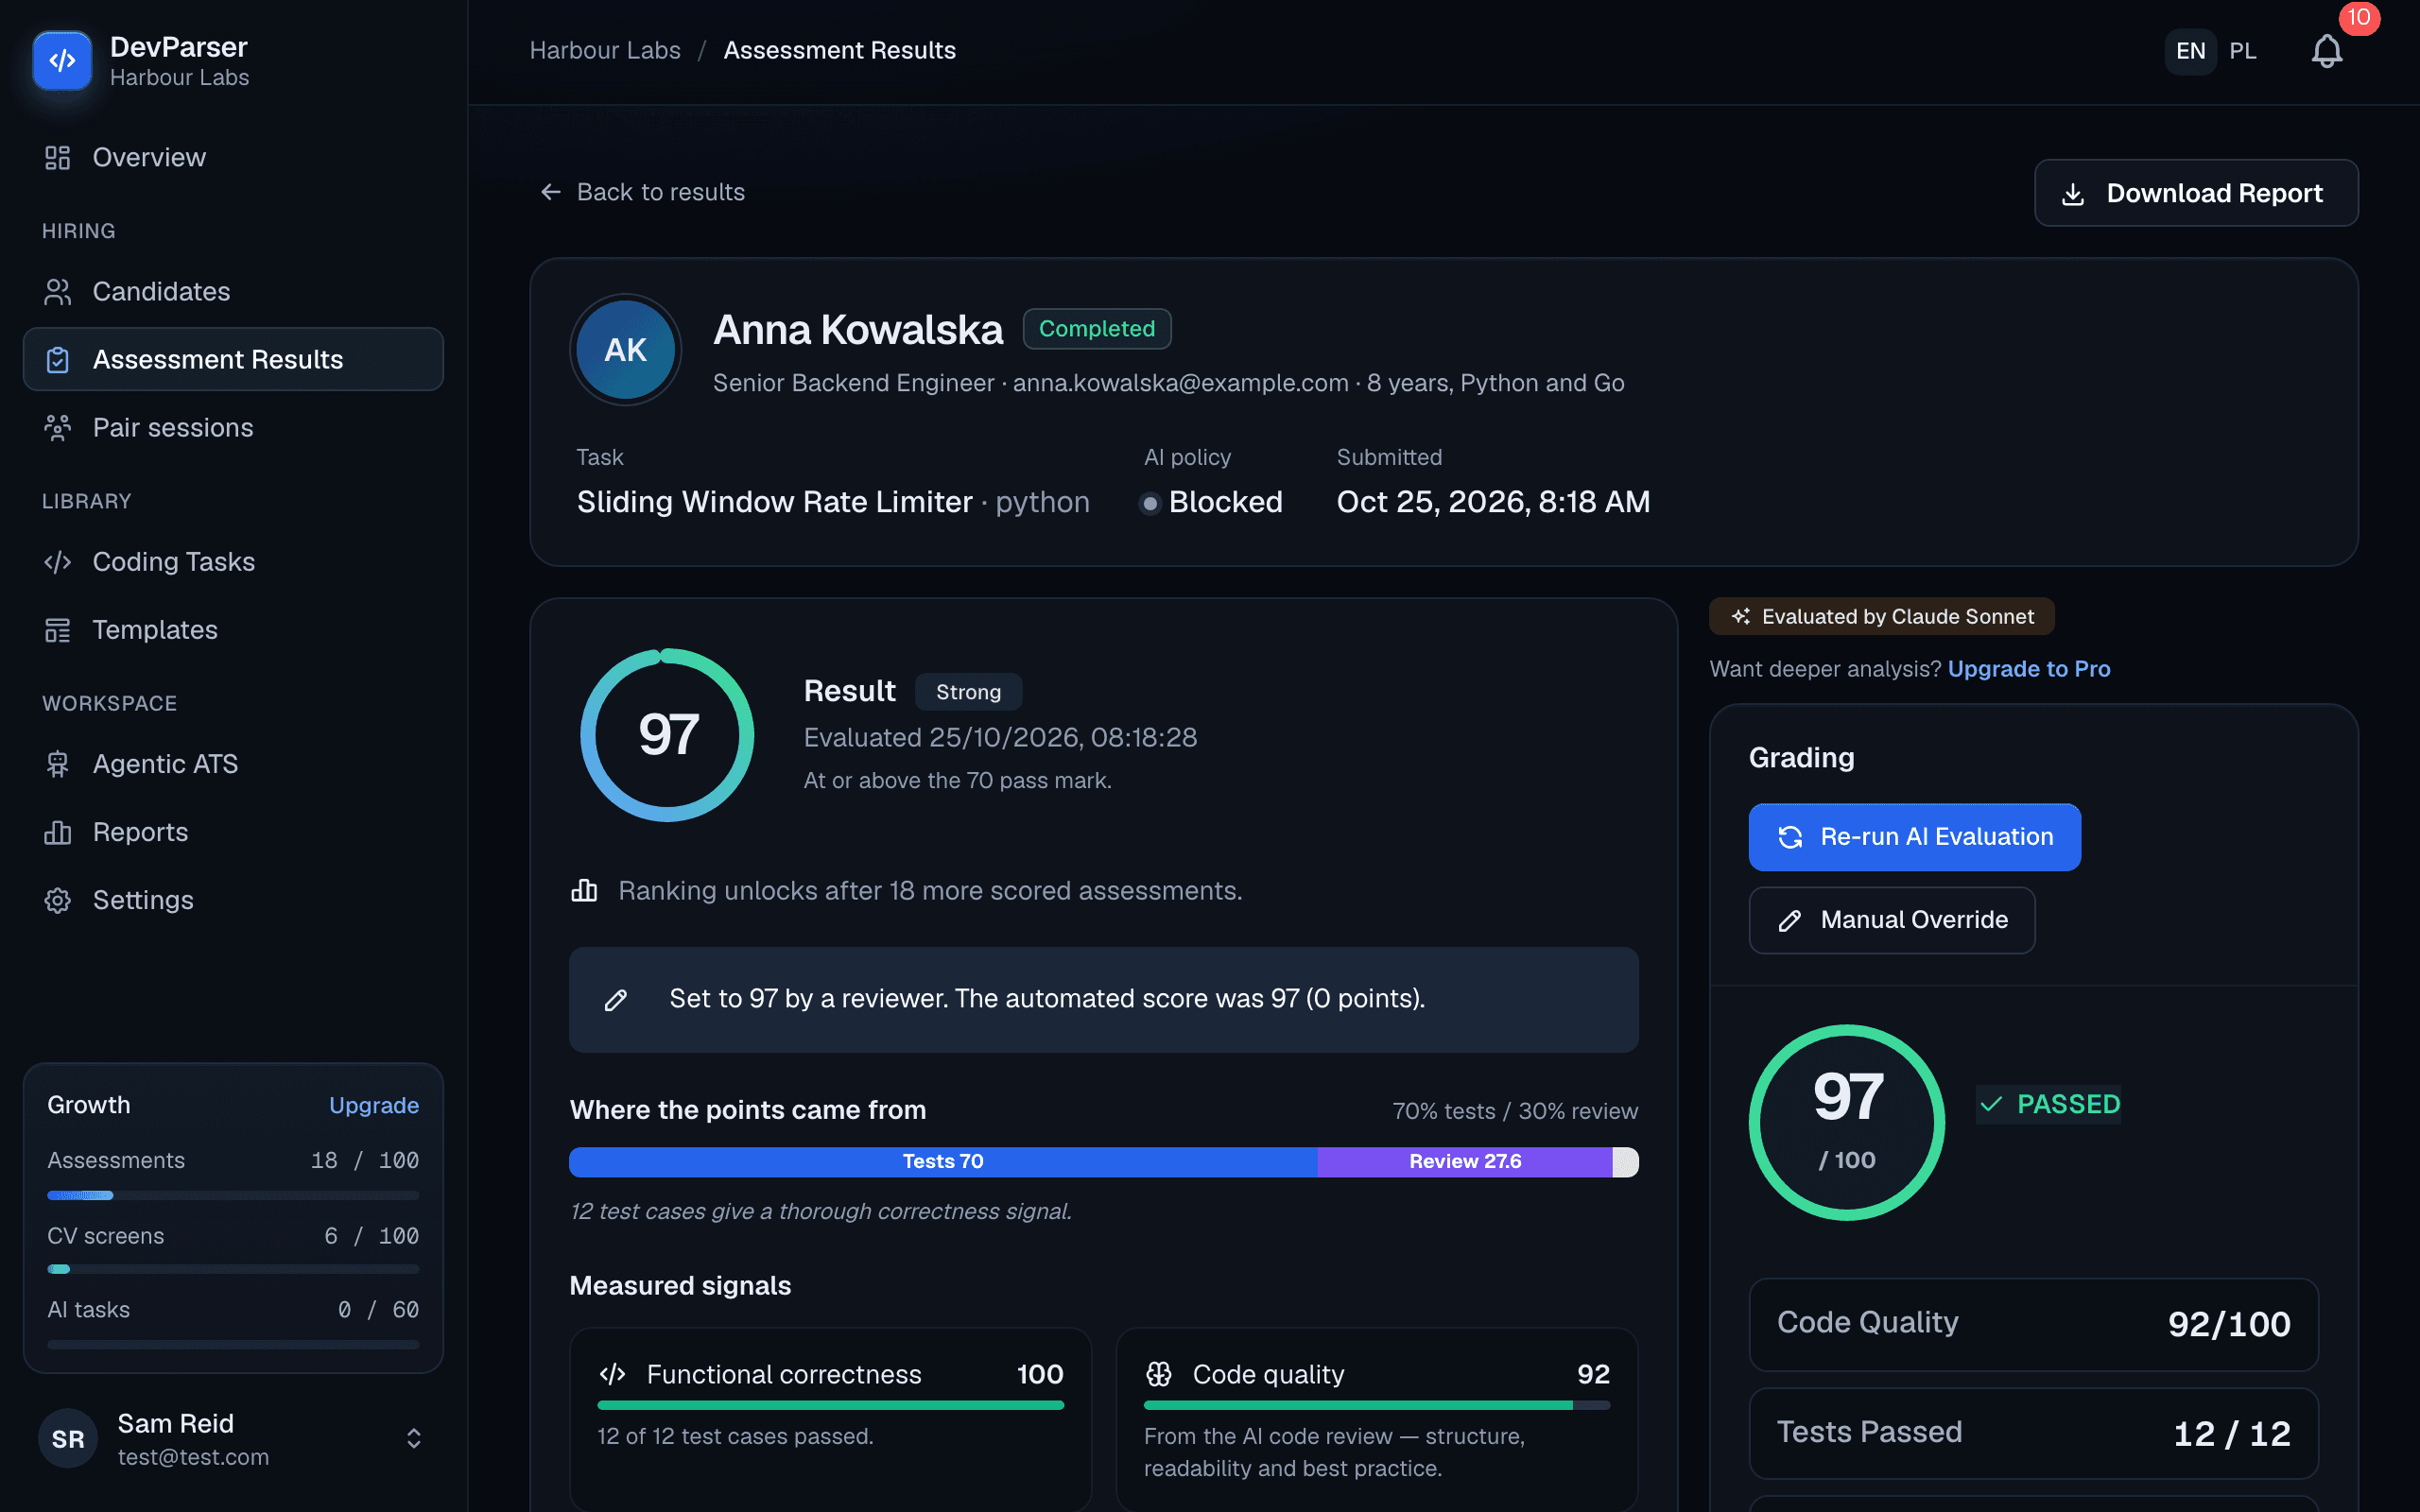
The screen a reviewer decides from: the score and how it was composed, hidden-test results, how the code was written and every test run before submit.
Screen a CV right now
Paste or upload one CV and see what comes back. It catches CVs pasted straight out of a model — and we publish the measurement, including where it fails. It runs in the browser and needs no account.
Drop in one CV
PDF or pasted text. Use a real one from a pile you are working through — that is the only way to know if this is worth anything to you.
Measured, and we publish it
In testing it flagged 27 of 32 unedited AI CVs and none of 36 human ones, measured against 99 labelled CVs. A candidate who asks the model to sound human gets past it — that is in the write-up too.
Nothing is kept
The CV is screened and discarded. It is not stored, not used to train models, and no account is created.
One CV at a time here, five an hour. For a whole pile use the free pile screener at devparser.it/tools/cv-pile — up to 25 CVs per run, no account.
Read the write-up: how we measured it, and where it failsHow it works in 4 steps
From invite to hire — take-home evidence and interview in one place
01
Bring your task, or make one
Paste in the take-home you already use and we pull the fields out of it for you to check. Or start from the template library, or generate a fresh challenge per candidate. Set the test cases, difficulty, language and time limit.
02
Invite Candidates
Send assessment links via email, ATS, or URL. Candidates use the secure editor, upload a zip, or paste a public git repo for take-home work.
03
Review Execution + AI Results
Candidate code runs against your hidden test cases. Claude then rates quality, efficiency and best practices. You get test results, AI reasoning, integrity evidence (process plus plagiarism signals) and a ranked list — ready to act on. Optionally, the candidate then answers written questions about their own code.
04
Pair with the finalists on one link
Open a shared editor and send the candidate one link. They join without an account or an install, you both type in the same file in real time, and the session is saved when it ends. A good live round asks them to extend the take-home they already wrote. On every plan, including the trial.
Anyone can pass a take-home with an LLM. See how the work was actually done.
Process evidence first, classifiers second. We fuse editor telemetry, public-git commit history, peer similarity and web/repo search — and deliberately cap style-only AI guesses so they never decide alone. A zip with nothing to corroborate it stays unverified; it never scores “clean”.
Secure editor and session telemetry on every plan · AI analysis layers and AI-allowed mode with a full prompt transcript on Growth and above · Public git process evidence on every submission path
Secure editor, or AI allowed on the record
Your choice per invitation. Blocked: copy and paste are refused and every attempt is logged, clipboard size included. Allowed (Growth and above): the candidate gets an AI assistant inside the editor, every prompt and reply is recorded, and the review adds a note on how well they used it.
Server-scored session telemetry (primary in-editor signal)
Paste volume, focus switches, typing rhythm, and whether the finished code traces back to keystrokes we actually observed, all re-scored on our servers. The reviewer also sees each time the candidate ran the visible tests and how many passed, so you can tell who tested as they went. Missing or stripped telemetry never scores clean.
Public git process evidence (take-home path)
Candidates can submit a public GitHub, GitLab, Bitbucket or Codeberg repo instead of a zip. We read its commit history and flag what doesn't look like a real working session: one bulk commit, a brand-new repo, work outside the assessment window, a different author. History can be rewritten, so we treat it as corroboration — never a sole reason to reject.
Cross-candidate similarity
Submissions are compared against other candidates at your company in the same language — same task and cross-task, with separate thresholds. With nothing to compare against, the check completes as no match instead of hanging. There is no shared public fingerprint corpus yet, so the first hire on a brand-new task starts without a baseline.
Public repository search
Two distinctive lines of a submission are looked up together in public GitHub repositories. When a file contains both, the repository link ships with the flag. This is verbatim search — a reworded copy is not caught, and a solution too short to search is reported as unsearched.
Evidence, not verdicts
Every flag ships with reasoning, matched sources, and signal scores. Reviewers confirm or override; dispositions are logged for audit. DevParser never auto-rejects on anti-cheat alone.
Take-home screening that holds up in review
Real execution, a Claude review, and integrity evidence you can inspect — for teams that don't hire off timed quizzes.
<30s
Review time
Real execution engine with AI analysis
Candidate code runs against your hidden test cases, then the latest Claude models rate quality, correctness and efficiency in 30 seconds. Hard test results plus AI reasoning: one clear hiring signal.
ATS
Pipeline sync
Agentic ATS screening — fully hands-free
Connect your ATS and DevParser takes it from there. The agent syncs candidates, writes a task for the role, and queues the evaluation — no clicks required.
1 link
No candidate account
Live pair programming on a single link
Open a shared editor and send the candidate one link. They open it in a browser, you both type in the same document in real time, and the session is saved when it ends. On every plan, including the trial.
Works with your ATS
Connect your applicant tracking system in minutes. DevParser syncs candidates and can run automated coding assessments — no manual imports.
Greenhouse
Lever
Workable
Recruitee
Teamtailor
BambooHR
Ashby
Recruit CRM
Bullhorn
Vincere
JobAdder
eRecruiter
Traffit
Don't see yours? More integrations are on the roadmap:
Hire better developers. Without wasting senior time.
Start with a 14-day trial — 10 assessments and 50 CV screens, no credit card. Then pick the plan that matches your hiring volume. Prefer no clock at all? The Free plan gives you 3 assessments a month.
Plan details are standard package defaults and may be adjusted by contract. · Security & compliance
Starter
For small agencies & startups
Claude Haiku
$99
/month
30 assessments/month
20 AI task generations
Code execution + Claude Haiku analysis
Secure editor + behavioral session telemetry
CV parsing & extraction
ATS sync — automated screening
Email support
2 team members
Your logo on candidate reports
Growth
For software houses & growing teams
Claude Sonnet
$499
/month
100 assessments/month
60 AI task generations
Code execution + Claude Sonnet analysis
Peer similarity, public repository search and public-git process evidence
ATS integration — automated screening
Priority support
5 team members
Advanced reporting
Your logo on candidate reports
Professional
For high-volume teams and agencies
Claude Opus
$999
/month
250 assessments/month
150 AI task generations
Code execution + Claude Opus deep analysis
Peer similarity, public repository search and public-git process evidence
ATS integration — automated screening
Custom API access & integrations
Dedicated support
15 team members
Advanced analytics & reporting
Your logo on candidate reports